Windows 11, and an honest scorecard
- Why LLMKIT: sharing what works across five stacks
- Context is the hard part
- The fourth and fifth stack
- The boring 20% that made it stick
- One view across Claude Code, Codex and Copilot
- Copy, never move
- Normalize once, at the end
- Windows 11, and an honest scorecard
- Shippable, with findings
- Mirror, don't ask
- A name isn't enough
- A footer means it finished
LLMKIT just picked up a sixth environment: Windows 11, alongside the five stacks it already spans.
The audit
A platform-parity audit compared how the kit behaved on macOS with how it behaved on Windows. It surfaced seven gaps, across:
- CLI scripts
- Scheduling
- Compilation
- Update detection
We fixed what the audit found — and then verified against Windows 11 directly, instead of assuming the fixes held.
The results
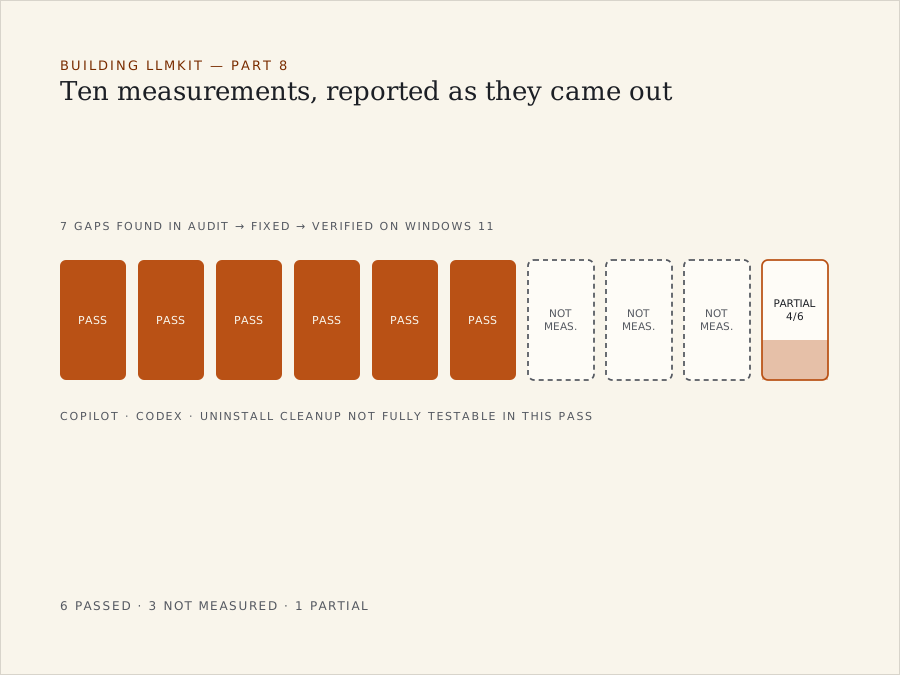
Ten measurements:
- 6 passed cleanly.
- 3 came back “not measured” — Copilot, Codex and uninstall cleanup weren’t fully testable in that pass.
- 1 was partial — 4 of 6 feeds pre-scheduled as expected.
Why report it this way
We could have rounded that up to “Windows support: done.” We didn’t.
“Not measured” isn’t the same as “passed,” and “partial” isn’t the same as “working.” Collapsing them hides exactly the information the team needs to decide what to test next. The honest version — what passed, what didn’t get measured, what’s still partial — is more useful than a clean bill of health that isn’t quite true yet.